
Block GPTBot in robots.txt: Minimal Template
Use this template when your specific goal is to disallow GPTBot sitewide. It targets OpenAI’s training crawler only; it does not automatically block OAI-SearchBot, which controls ChatGPT Search crawling.
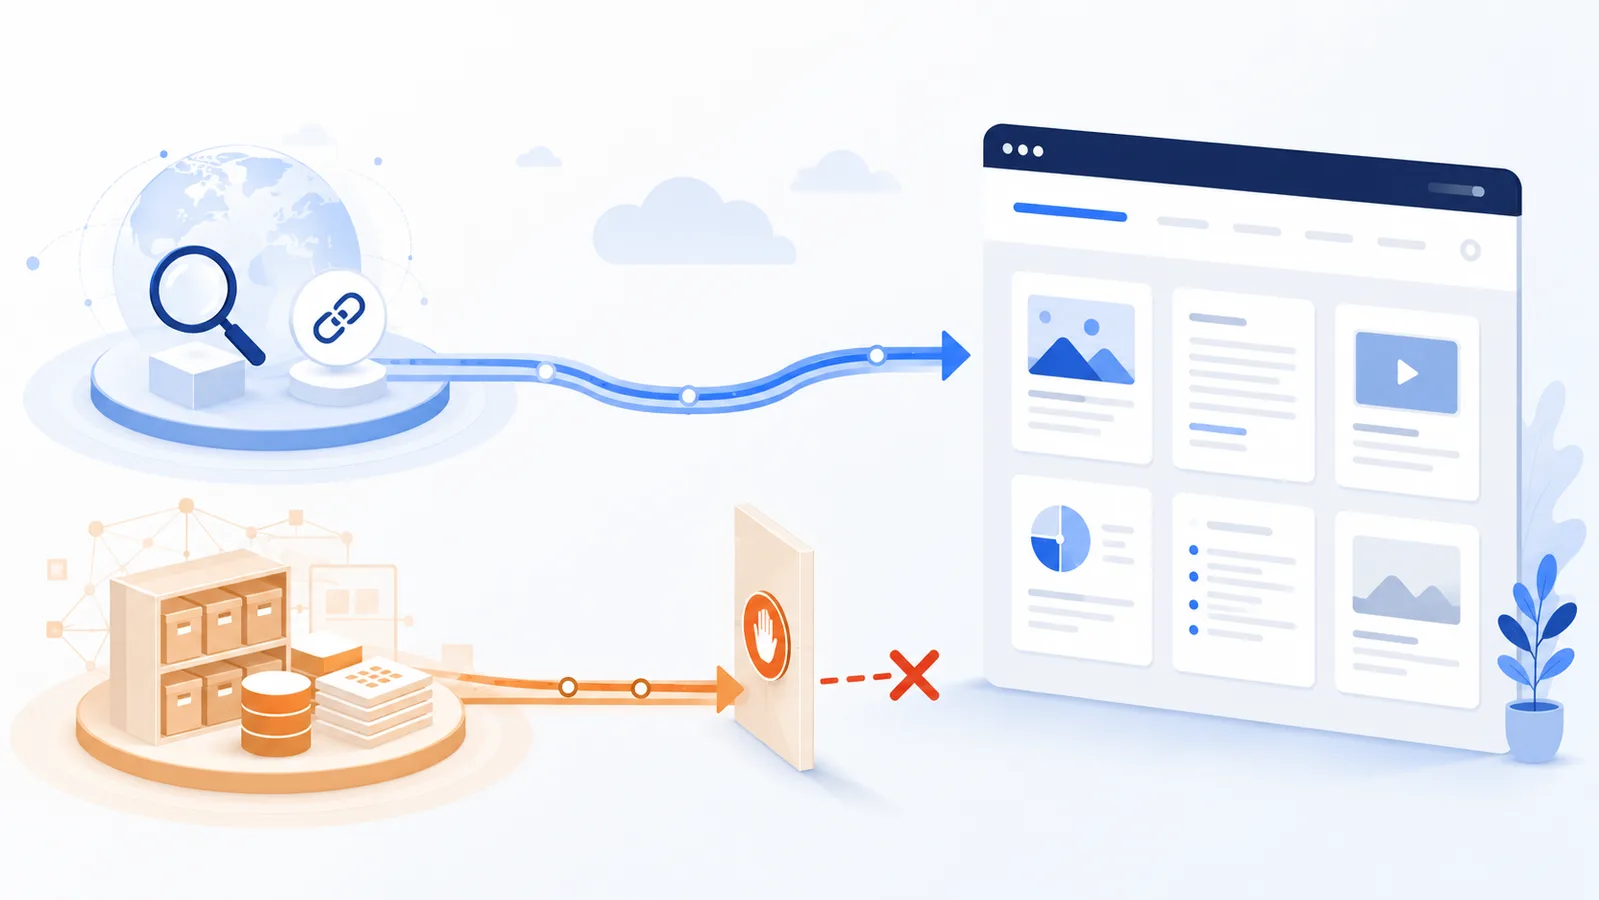
Copy-paste robots.txt example
User-agent: GPTBot
Disallow: /
This is the smallest sitewide rule for the specific intent “block GPTBot”:
User-agent: GPTBot
Disallow: /
What this template blocks
The rule targets GPTBot, OpenAI’s crawler for content that may be used in generative AI foundation-model training. It does not create a provider-wide OpenAI block.
In particular, it does not automatically block OAI-SearchBot. That lets a publisher make a separate decision about appearing in ChatGPT Search.
Keep ChatGPT Search open if you want discovery
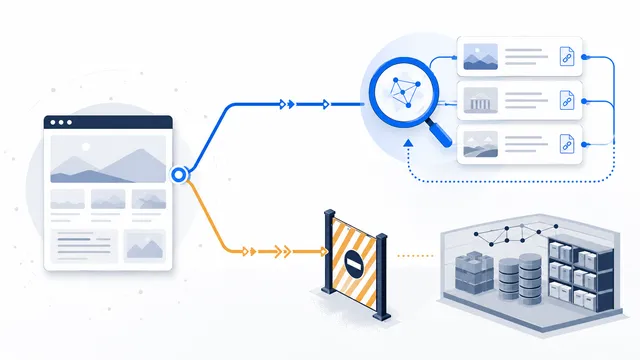
If your policy is “no GPTBot training crawl, but keep ChatGPT Search eligibility,” make the distinction explicit:
User-agent: GPTBot
Disallow: /

User-agent: OAI-SearchBot
Allow: /
OpenAI documents these controls independently. Do not add extra OpenAI user agents unless you have a separate reason for each one.
Test a real site policy rather than just the homepage
A site that blocks GPTBot from / can still have unrelated rules for other agents. Build the merged draft first, then test it with draft Checker using GPTBot and OAI-SearchBot for /, plus a private path such as /account/profile.
| Crawler | Path | Intended result with the example above |
|---|---|---|
| GPTBot | / | Blocked |
| OAI-SearchBot | / | Allowed by the example |
| OAI-SearchBot | /account/profile | Allowed unless you add a specific restriction |
The final row is why copy-pasting only an Allow: / group can be unsafe for an existing configuration: specifically matched groups do not inherit a wildcard group’s path restrictions. Review the live rules, carry forward site-specific protections and re-test before deployment. Robots.txt never replaces authentication.
Before you paste it
- Merge the group into your existing
/robots.txt; do not overwrite unrelated search-engine rules. - Keep any existing
Sitemap:directives and platform-specific rules. - Publish the file on the exact hostname you want to control.
- Open the live file in a browser and test a public URL with the robots.txt Checker.
Need a broader OpenAI policy?
If your real requirement is to make different decisions for training and ChatGPT Search, use the OpenAI robots.txt controls template. If you want the factual reference behind this snippet, see GPTBot.
Block only part of the site
You do not have to disallow GPTBot everywhere. If only a specific public section should be excluded from GPTBot crawling, use a path rule instead:
User-agent: GPTBot
Disallow: /research-archive/
Test both a URL inside the blocked path and a normal public URL outside it. This catches prefix and path-matching mistakes before they affect more of the site than intended.
FAQ
Does blocking GPTBot block ChatGPT search?
No. OpenAI documents OAI-SearchBot as an independent search crawler. Keep OAI-SearchBot allowed if you want your pages eligible for ChatGPT search discovery.
Does blocking GPTBot remove previously collected content?
The robots.txt rule controls future compliant crawling. It does not by itself remove content collected before the rule was published.
How long does a GPTBot robots.txt change take to apply?
Provider systems need time to refresh robots.txt. OpenAI notes an adjustment period for crawler settings, so verify the public file and allow time for the change to propagate.
Can I block GPTBot only from selected directories?
Yes. Use path-specific Disallow rules for stable content areas, but protect genuinely private material with authentication rather than relying on a public path list.
Does GPTBot obey a wildcard group?
A wildcard group can apply when there is no more specific matching GPTBot group, but a dedicated GPTBot group is clearer and prevents accidental policy changes when other rules are edited.
 GPTBot: robots.txt Rules for OpenAI Training Crawling
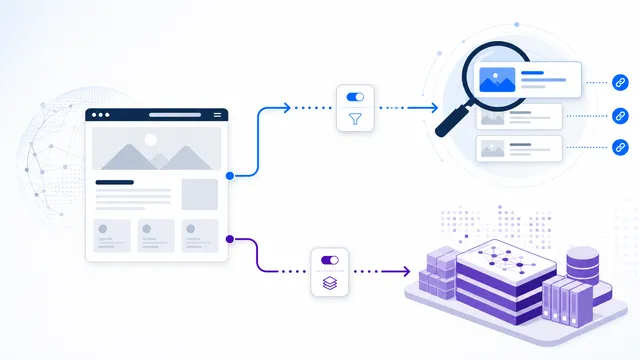 GPTBot vs OAI-SearchBot: Training vs Search
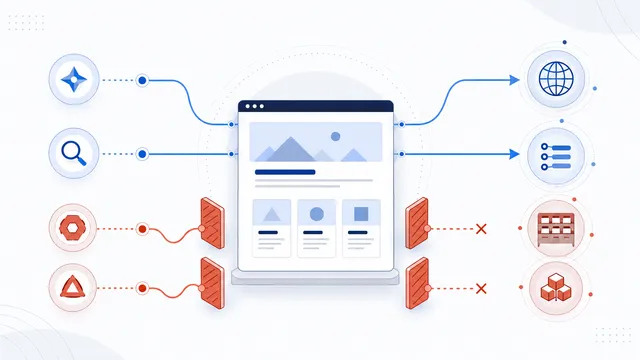 How to Block AI Crawlers with robots.txt
 How to Allow AI Search but Block AI Training
 robots.txt Checker