
GPTBot robots.txt: Control OpenAI Training Crawling
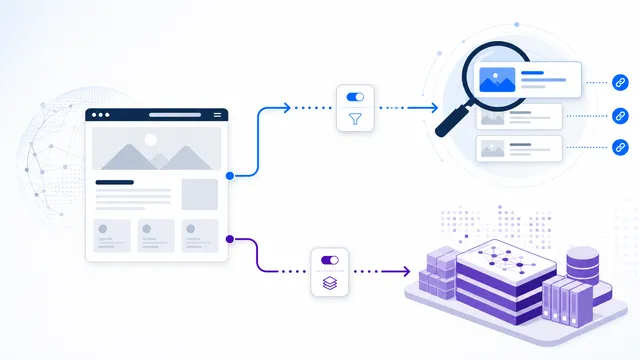
GPTBot is OpenAI’s crawler for content that may be used to improve and train generative AI foundation models. Its robots.txt control is independent from OAI-SearchBot, which is used for ChatGPT Search visibility, and from user-triggered ChatGPT-User requests.
Primary reference
Official crawler documentation
Use the provider's current documentation to confirm the crawler token and purpose before changing a production robots.txt file.
First-party crawler telemetry
Observed on Robots.txt Lab
Aggregate requests that claimed this crawler identity while visiting this site during the last 90 days.
/sitemap.xml82/4/ai-crawlers/claude-searchbot3/checker3
Verification note: User-Agent strings can be spoofed. These are aggregate requests that claimed the crawler name, not proof that every request came from the provider's verified infrastructure.
Copy-paste robots.txt example
User-agent: GPTBot
Disallow: /
GPTBot has one specific job: it crawls public web content that may be used to improve and train OpenAI’s generative AI foundation models. That makes the decision about GPTBot a data-use decision, not a general “block ChatGPT” switch.
Three acceptance tests for a GPTBot policy
Before changing a live robots.txt file, decide whether you want to block training crawling while keeping search discovery available. In the draft tester, evaluate the two product tokens separately against the same path; a test of GPTBot cannot establish what OAI-SearchBot will do.
User-agent: GPTBot
Disallow: /

User-agent: OAI-SearchBot
Allow: /| Test | Expected result | Why it matters |
|---|---|---|
GPTBot on /articles/example | Blocked | Expresses the training-crawl opt-out. |
OAI-SearchBot on that path | Allowed | Does not opt the site out of ChatGPT Search. |
Googlebot on that path | Allowed unless another rule blocks it | Checks ordinary search crawling separately. |
After publishing, repeat the checks against the server's actual /robots.txt response. The published file may be replaced by a CDN, a CMS plugin or a security layer. For real request attribution, compare IP addresses against OpenAI's published crawler IP lists; a User-Agent header alone can be spoofed.
What GPTBot controls
A rule for GPTBot tells OpenAI whether this crawler may fetch your pages for the training-related purpose described in OpenAI’s crawler documentation. A site can allow GPTBot, block it sitewide, or restrict selected paths.
User-agent: GPTBot
Disallow: /
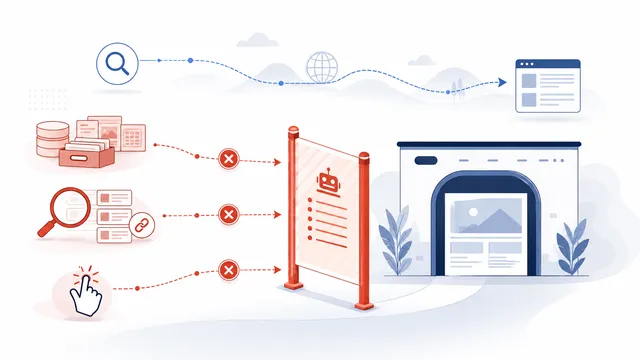
That rule does not automatically block every OpenAI user agent. OpenAI separates its crawler controls by purpose.
GPTBot vs OAI-SearchBot vs ChatGPT-User
- GPTBot — automatic crawling for content that may contribute to generative AI model training.
- OAI-SearchBot — automatic crawling used to surface sites in ChatGPT Search. You can allow this while blocking GPTBot.
- ChatGPT-User — fetches that can happen because a user asked ChatGPT to access a page. OpenAI says these user-triggered requests are not automatic web crawling and robots.txt rules may not apply.
Choose the rule by outcome
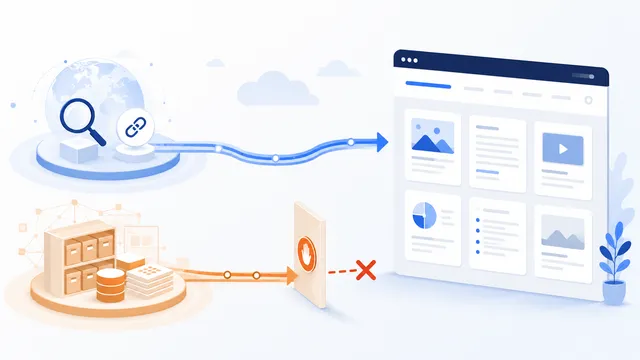
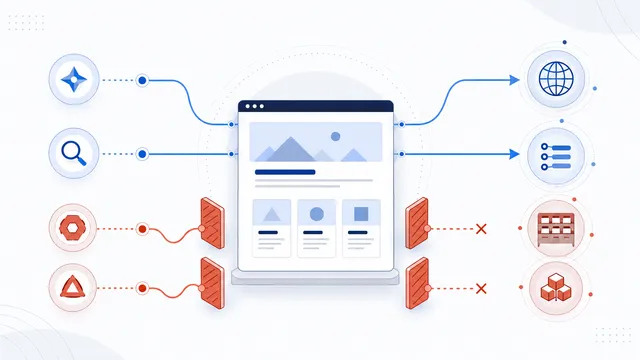
If your goal is to keep eligibility for ChatGPT Search while opting out of OpenAI training crawling, use separate groups: allow OAI-SearchBot and disallow GPTBot. If your goal is only to block GPTBot, use the smallest rule that expresses that choice rather than a provider-wide block.
For a ready-to-paste version, use the Block GPTBot template. For a broader comparison of OpenAI controls, see OpenAI robots.txt controls.
Verify the result
After publishing, open /robots.txt on the live hostname, confirm the GPTBot group is present, and test a representative URL with the robots.txt Checker. Remember that robots.txt is a crawl policy, not authentication: a client can spoof a User-Agent, so use server or WAF controls when you need enforceable access restrictions.
FAQ
Does blocking GPTBot also remove my site from ChatGPT search?
No. GPTBot and OAI-SearchBot are separate controls. You can block GPTBot for training purposes while allowing OAI-SearchBot for ChatGPT search visibility.
Does a GPTBot block delete content already learned by a model?
No. A robots.txt rule controls future compliant crawling. It is not a retroactive deletion request and does not remove copies held by other websites or services.
Can I block GPTBot only from selected folders?
Yes. Use path-specific Disallow rules under the GPTBot group. Private or sensitive folders must still be protected with authentication because robots.txt is publicly readable.
Should I block GPTBot with User-agent: *?
Usually not when GPTBot is your only concern. A wildcard block may also affect search engines and other compliant crawlers. Use the specific GPTBot token for a targeted policy.
How can I verify a request that claims to be GPTBot?
Check the request against OpenAI’s current published IP ranges and review the user-agent in your server logs. A user-agent string by itself can be spoofed.
 OAI-SearchBot robots.txt Guide
 Block GPTBot: Minimal robots.txt Template
 OpenAI robots.txt Controls: Training vs ChatGPT Search
 GPTBot vs OAI-SearchBot: Training vs Search
 How to Block AI Crawlers with robots.txt