
Sitemap Directive in robots.txt
The Sitemap directive is a widely supported robots.txt extension that tells crawlers where a site’s XML sitemap or sitemap index can be found. Use an absolute URL. It advertises the sitemap location but does not force crawling or indexing.
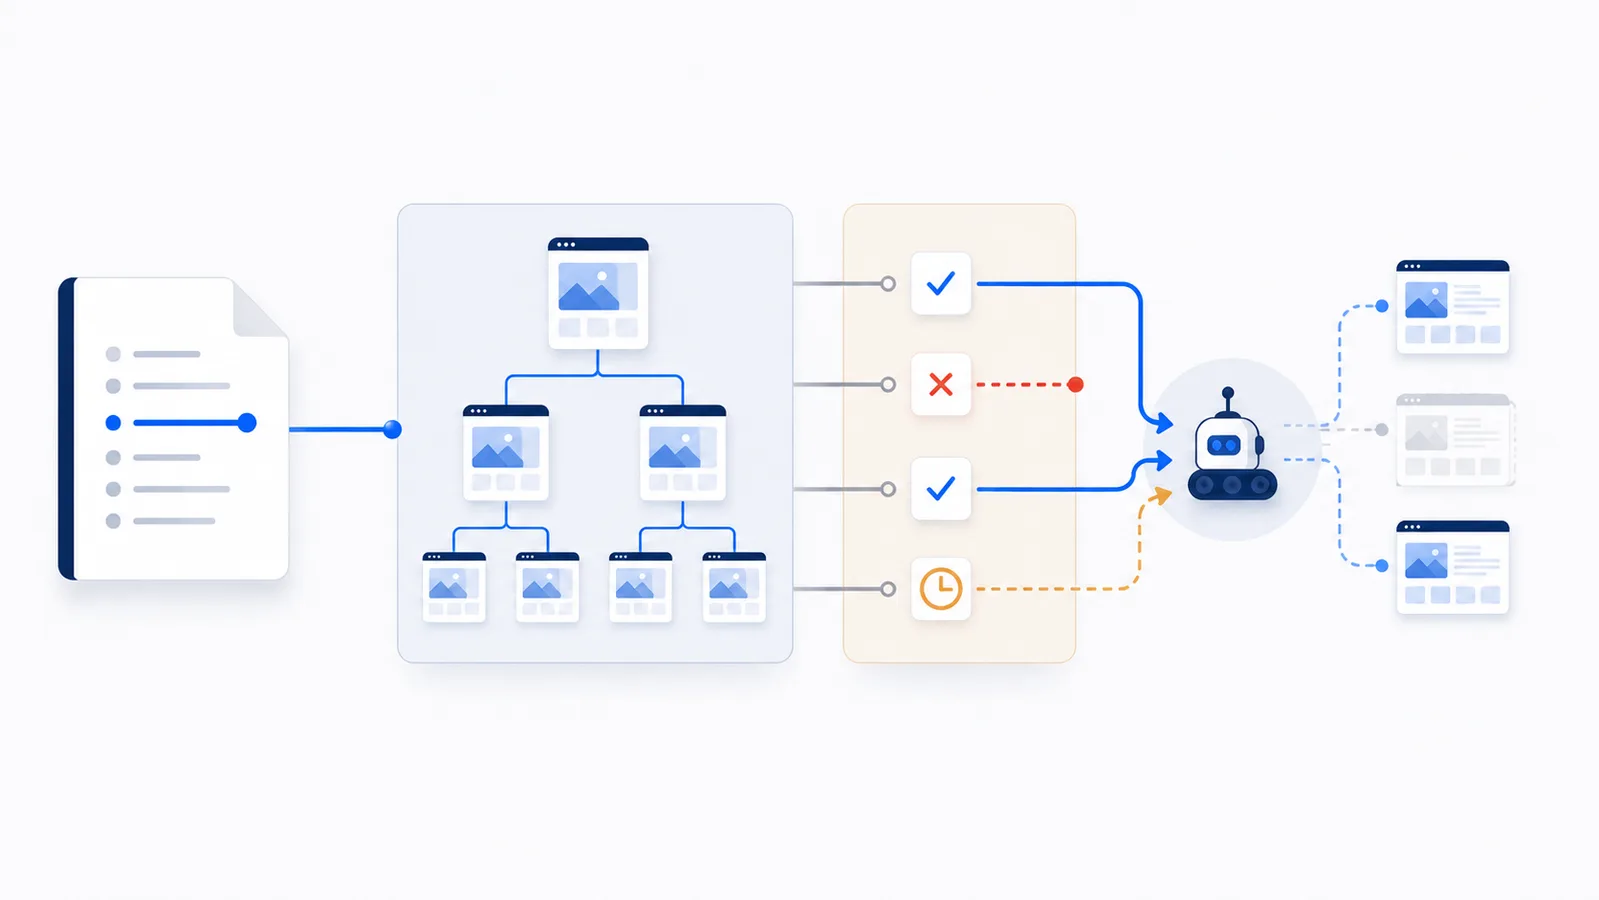
Copy-paste robots.txt example
User-agent: *
Allow: /

Sitemap: https://example.com/sitemap.xml
Sitemap: https://example.com/news-sitemap.xml
The Sitemap: directive points crawlers to a sitemap URL. It is a discovery hint placed in /robots.txt, not an Allow/Disallow rule.
Syntax
Sitemap: https://www.example.com/sitemap.xmlUse an absolute URL including https:// and the hostname. The target can be a sitemap file or a sitemap index.
Multiple Sitemap lines
A robots.txt file can advertise more than one sitemap:
Sitemap: https://www.example.com/sitemap-pages.xml
Sitemap: https://www.example.com/sitemap-products.xml
It is not part of a User-agent group
The directive identifies sitemap locations for the site; it is not a path rule scoped to the nearest User-agent. It can appear alongside crawler groups in the same file.
What Sitemap does not guarantee
- It does not force a crawler to fetch the sitemap immediately.
- It does not guarantee every URL in the sitemap will be crawled.
- It does not guarantee indexing or ranking.
- It does not override a robots.txt block on a URL.
Which sitemap address should the directive contain?
If your website exposes a sitemap index (one XML document listing multiple sitemap XML files), point the directive to the index rather than copying each child entry. For example:
Sitemap: https://www.example.com/sitemap.xmlOpen that URL and check that its <loc> entries resolve to real child sitemaps. If you have only a single sitemap, point the directive directly to that file. This directive does not belong to any one user-agent group and does not grant crawl permission for pages whose applicable rule is Disallow. For the full procedure, see how to add and validate a sitemap in robots.txt.
Related task
If you are implementing this on a real site, including multiple sitemaps, CMS-generated robots.txt, hostname checks and verification steps, use the practical guide How to add a sitemap to robots.txt. For the broader file format, see What is robots.txt?.
Placement and validation
The directive is commonly placed near the end of robots.txt for readability, but its usefulness depends on the URL being correct, not on a special position in the file. After editing, open both /robots.txt and the advertised sitemap URL. A typo, staging hostname, HTML error page or broken redirect makes a syntactically correct Sitemap line operationally useless.
FAQ
Does the Sitemap directive belong inside a User-agent group?
No. Sitemap is a standalone record, not an Allow or Disallow rule for one crawler group. It is commonly placed at the end of robots.txt for readability.
Can I add more than one Sitemap line?
Yes. You may list multiple absolute sitemap URLs, although a sitemap index is often easier to manage when a site has many sitemap files.
Does a sitemap override a Disallow rule?
No. A crawler that honors robots.txt should still respect the matching Disallow rule even when the blocked URL appears in a sitemap.
Will adding Sitemap guarantee that pages are indexed?
No. It helps crawlers discover URLs, but crawling and indexing remain subject to access, canonicalization, response quality, content quality, and each engine’s own priorities.
Should I still submit the sitemap in webmaster tools?
You can. Direct submission in Google Search Console or Bing Webmaster Tools provides reporting, while the robots.txt directive offers automatic discovery. The methods can be used together.
 How to Add a Sitemap to robots.txt and Verify It
 What Is robots.txt? Scope, Rules and Limitations
 robots.txt Checker
 robots.txt HTTP Status Codes: 200, 3xx, 4xx, and 5xx
 Common robots.txt Mistakes and How to Fix Them