
How to Add a Sitemap to robots.txt
Add an absolute Sitemap URL to robots.txt, then verify that both the robots.txt file and the sitemap resolve on the intended production hostname. The directive helps crawlers discover the sitemap; it does not guarantee crawling or indexing.
Copy-paste robots.txt example
User-agent: *
Allow: /

Sitemap: https://www.example.com/sitemap.xml
This guide is for the practical task “put my sitemap in robots.txt and make sure it works.” If you only need the syntax definition, see the Sitemap directive glossary.
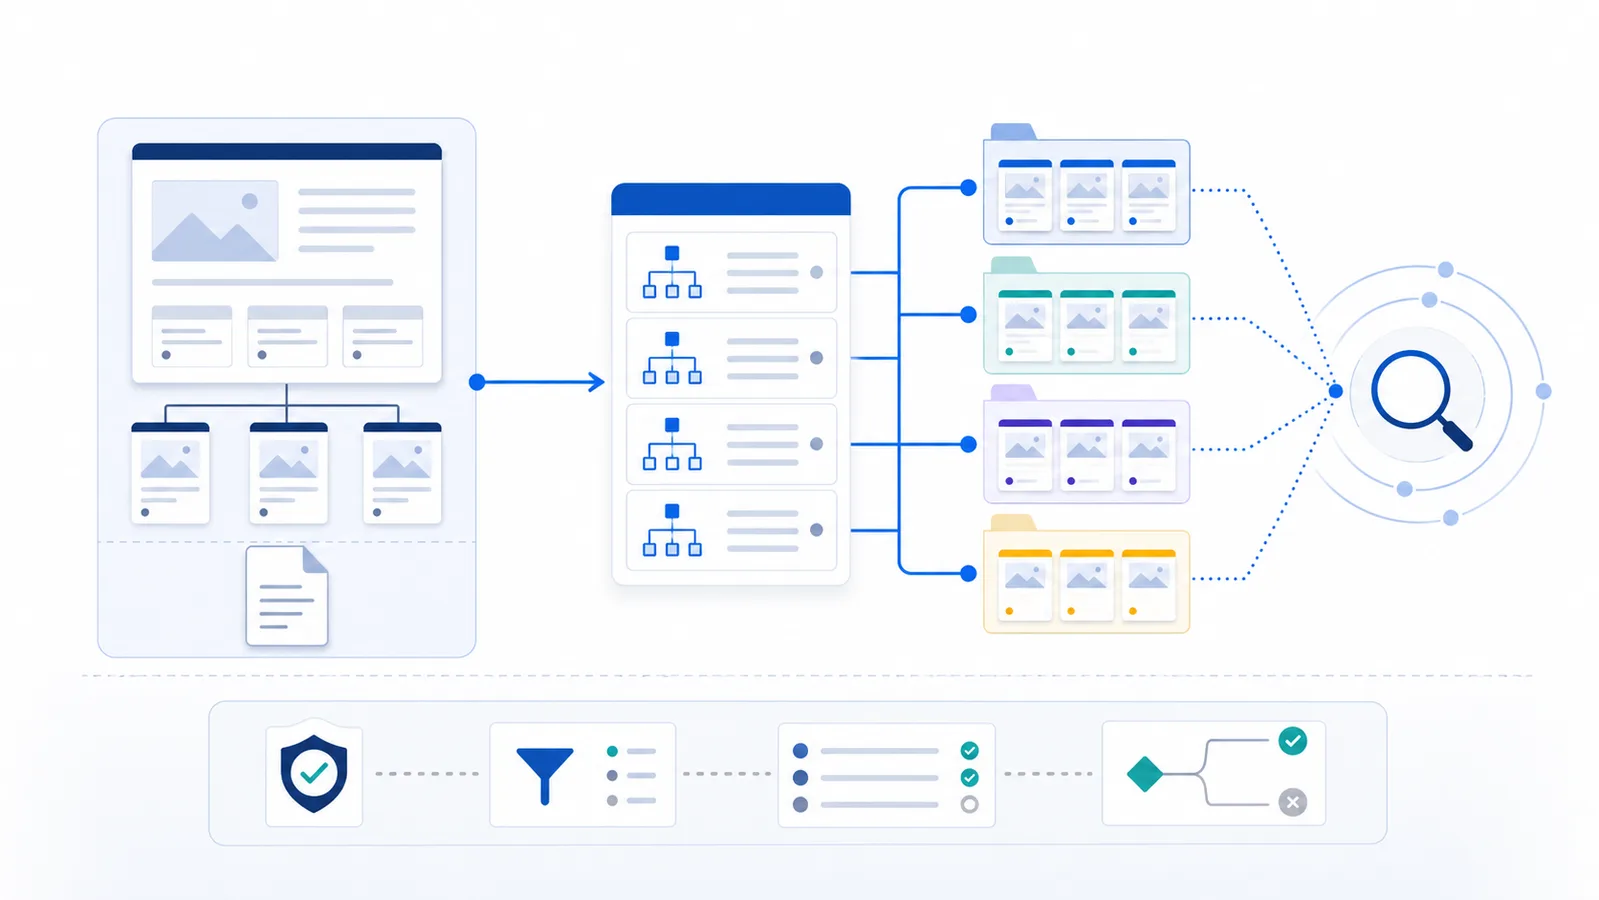
Validate sitemap-index references without confusing the two XML layers
A root file such as /sitemap.xml may be a sitemap index, not a list of page URLs. For example, an index can contain /sitemap-pages.xml and /sitemap-guides.xml. Each child then lists the actual canonical page addresses. It is normal that a page URL cannot be found by searching inside the root index itself.
- Open the root sitemap and identify whether its top element is
sitemapindexorurlset. - If it is an index, open the relevant child sitemap and locate the exact page's
<loc>. - Confirm that each page URL returns its intended 200 response and does not carry an accidental
noindex. - Use
<lastmod>for significant page changes when it truthfully reflects them; do not refresh every date merely to attract crawlers. - Submit the root index in webmaster tools. Submitting every child is normally unnecessary if the root lists them.
Neither the sitemap directive in robots.txt nor sitemap submission can force a search engine to index a URL. The distinction matters when investigating Discovered – currently not indexed versus Crawled – currently not indexed. The former can be a discovery/scheduling issue; the latter means the URL was fetched but not selected for indexing.
1. Find the real sitemap URL
Open the sitemap in a browser first. Common examples are /sitemap.xml, /sitemap_index.xml, or a CMS-specific path. The URL must be reachable on the production hostname you want crawlers to use.
2. Add an absolute Sitemap directive
User-agent: *
Allow: /

Sitemap: https://www.example.com/sitemap.xml
Use a full absolute URL including the scheme and hostname. The Sitemap: line is not tied to the preceding User-agent group; it is a file-level sitemap declaration.
3. Multiple sitemaps are allowed
If the site exposes multiple independent sitemap files, add multiple lines:
Sitemap: https://www.example.com/sitemap-pages.xml
Sitemap: https://www.example.com/sitemap-products.xml
If you already have a sitemap index that references child sitemaps, one directive pointing to the index is normally simpler.
4. Verify both endpoints
/robots.txtshould return the updated plain-text file.- The Sitemap URL should return the real XML sitemap, not an HTML error, login page or redirect loop.
- The hostname should match the production site you intend to crawl.
- Do not leave staging or localhost sitemap URLs in production.
5. Check for CMS or CDN overrides
Some CMS platforms generate robots.txt dynamically, and a plugin, reverse proxy, CDN or server file can override what you edited. Always verify the live response, not just the configuration screen where you made the change.
What the directive does not do
A Sitemap line improves discovery of the sitemap location, but it does not force a search engine to crawl every URL or include every page in its index. Indexing still depends on crawlability, canonical signals, content quality and the search engine’s own systems.
After publishing, test the file with the robots.txt Checker. For the concise syntax reference, use Sitemap directive.
FAQ
Where should the Sitemap line go in robots.txt?
It may appear anywhere because it is a standalone record rather than part of a User-agent group. Many sites place it at the end for readability.
Can robots.txt contain multiple Sitemap lines?
Yes. You can list several absolute sitemap URLs. If a sitemap index already lists the individual files, one line pointing to that index is often simpler.
Should the Sitemap value be an absolute URL?
Yes. Use the complete URL including https:// and the host, for example https://example.com/sitemap.xml, rather than a relative path.
Does a Sitemap line override Disallow?
No. Sitemap helps URL discovery, while Allow and Disallow determine crawl permission for the matching crawler group. The access rule still applies.
Does adding a sitemap guarantee indexing?
No. It is a discovery hint. Search engines still evaluate crawl access, HTTP status, canonicalization, content quality, and their own indexing systems.
 Sitemap Directive in robots.txt: Definition and Syntax
 robots.txt Checker
 robots.txt HTTP Status Codes: 200, 3xx, 4xx, and 5xx
 robots.txt Wildcards: * and $ Pattern Matching
 Common robots.txt Mistakes and How to Fix Them