
ClaudeBot robots.txt Rules for Anthropic Training Crawling
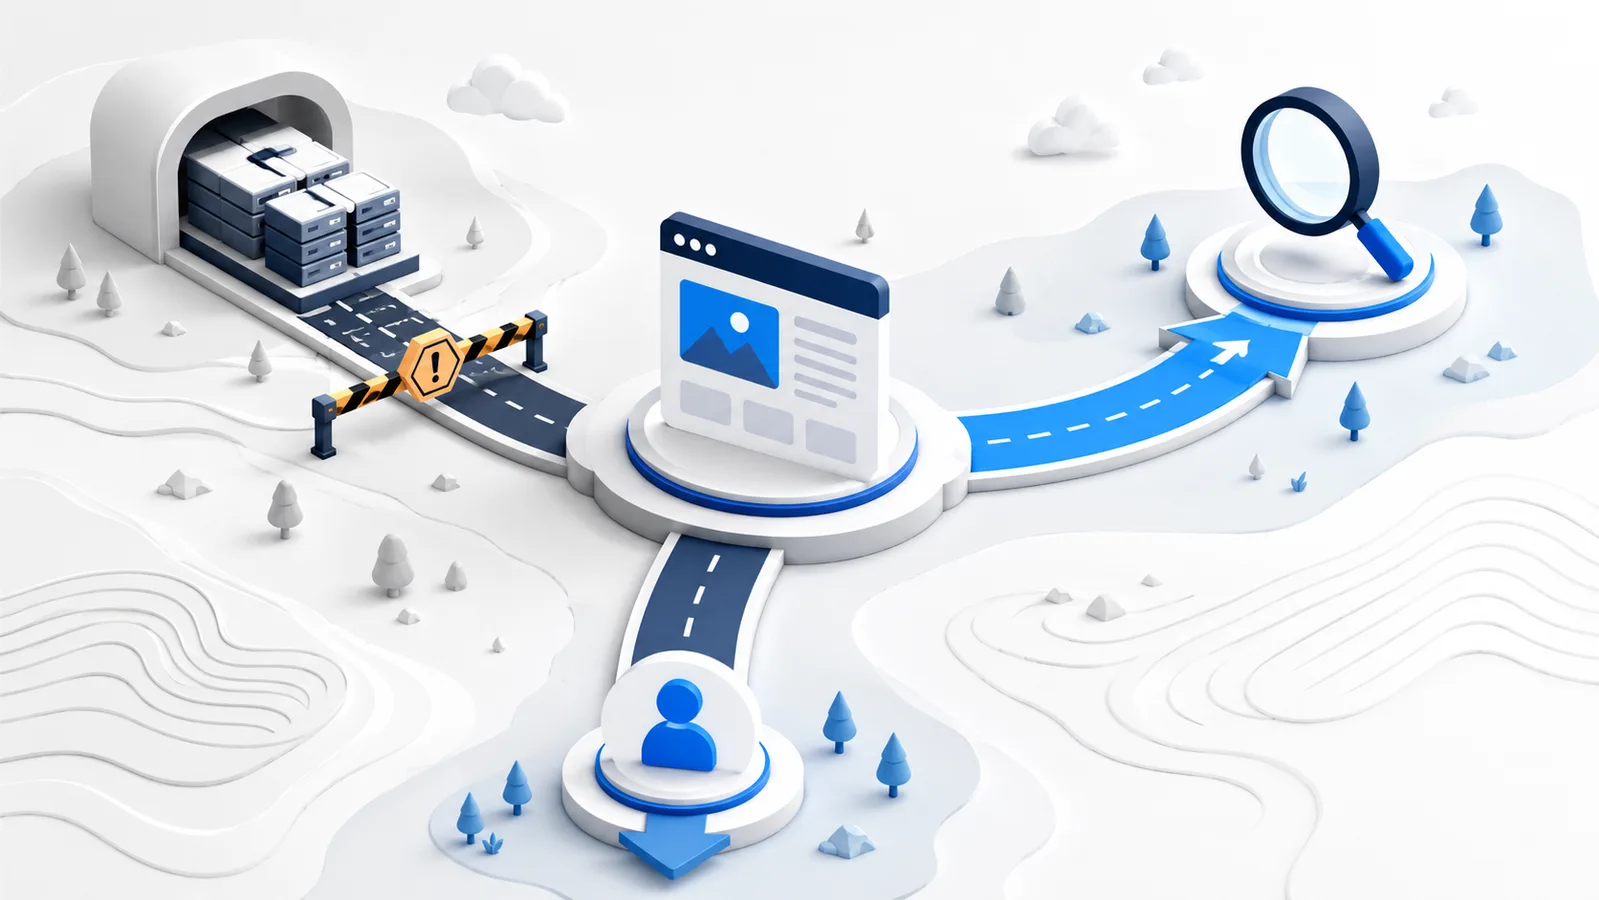
ClaudeBot is Anthropic’s crawler for public web content that may contribute to model development and training. A ClaudeBot-specific Disallow rule signals that future material should be excluded from Anthropic training crawls. Claude-SearchBot and Claude-User are separate agents with different purposes.
Primary reference
Official crawler documentation
Use the provider's current documentation to confirm the crawler token and purpose before changing a production robots.txt file.
First-party crawler telemetry
Observed on Robots.txt Lab
Aggregate requests that claimed this crawler identity while visiting this site during the last 90 days.
/robots.txt339/sitemap.xml336/guides/robots-txt-ai-search4/templates4
Verification note: User-Agent strings can be spoofed. These are aggregate requests that claimed the crawler name, not proof that every request came from the provider's verified infrastructure.
Copy-paste robots.txt example
User-agent: ClaudeBot
Disallow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: Claude-User
Allow: /
ClaudeBot’s role in Anthropic’s crawler system
Anthropic operates three documented robots with different jobs. ClaudeBot collects public web content that could contribute to model training and improvement. Claude-SearchBot supports search-result quality, while Claude-User retrieves pages in response to a person’s request.
Choosing which Claude crawler to restrict
Do not treat ClaudeBot, Claude-SearchBot and Claude-User as interchangeable. Consider a publication that wants to be discoverable in Claude search experiences but does not want automated training collection. The following policy expresses that specific objective, rather than a blanket ban on Anthropic:
User-agent: ClaudeBot
Disallow: /

User-agent: Claude-SearchBot
Allow: /
Test the policy with both tokens on / and one article path. Expected: ClaudeBot is blocked and Claude-SearchBot is allowed, provided no more-specific matching rules are present. Anthropic also documents Claude-User for user-initiated requests; decide on that access separately rather than assuming it inherits either group. An explicit token group should be tested independently of User-agent: *.
If you are trying to stop unauthorized access to an account, API or unpublished manuscript, robots.txt is the wrong boundary. The resource must be protected by authentication or server authorization. Confirm current token purposes with Anthropic's crawler documentation before publication.
Because the tokens are separate, a site owner can write a policy that blocks training crawling without automatically disabling Claude search discovery or user-directed retrieval. The example on this page shows that targeted approach.
Block ClaudeBot without overblocking
To opt an entire host out of ClaudeBot crawling, place a Disallow: / rule under User-agent: ClaudeBot. Apply the policy independently to every subdomain that needs the same restriction because each host can publish its own robots.txt file.
Avoid using only User-agent: * when your intention concerns Anthropic training crawling alone. A wildcard policy can affect ordinary search engines, monitoring tools, and other compliant bots. Keep Claude-SearchBot and Claude-User in separate groups when their access decision differs.
Anthropic also supports crawl pacing
Anthropic states that its bots honor standard robots.txt directives and supports the non-standard Crawl-delay extension. If server load rather than training permission is the problem, a measured crawl delay may be more appropriate than a complete site-wide block. Support for Crawl-delay is crawler-specific, so do not assume every search engine interprets it the same way.
A crawl-delay instruction and a disallow rule solve different problems: one limits request pace, while the other tells a compliant bot not to fetch matching paths.
Do not rely on IP blocking as the opt-out method
Anthropic advises site owners to express the opt-out in robots.txt. Blocking network addresses alone can prevent the bot from reading the policy and may not provide a persistent opt-out as address ranges change. IP information is still useful for authenticating log entries, but robots.txt should carry the crawler preference.
Recommended verification process
- Merge the ClaudeBot rule with the site’s existing robots.txt file.
- Decide separately whether Claude-SearchBot and Claude-User should be allowed.
- Publish the file at the root of each relevant host.
- Confirm that the URL returns the intended plain-text content and a successful response.
- Test the final rule with the robots.txt checker and review server logs after deployment.
The ClaudeBot vs Claude-SearchBot guide covers the policy split, and the Claude crawler template provides a broader starting point.
Anthropic’s current definitions, examples, and crawl-delay guidance are available in its official crawler guidance.
FAQ
Does blocking ClaudeBot also block Claude search?
Not automatically. ClaudeBot, Claude-SearchBot, and Claude-User are separate tokens. Set a separate rule for each purpose.
Can I slow ClaudeBot instead of blocking it?
Anthropic says its bots support the non-standard Crawl-delay extension. Use it when request pacing is the concern, and test the live behavior.
Do I need a ClaudeBot rule on every subdomain?
Yes, when each subdomain should have the same preference. Robots.txt is host-specific, so publish the appropriate file at the root of every relevant host.
Is blocking Anthropic IP addresses enough to opt out?
Anthropic recommends using robots.txt. IP-only blocking can stop the crawler from reading your policy and may not remain reliable when network ranges change.
Does a ClaudeBot rule remove material already used in training?
The rule signals that future materials on the blocked host or path should be excluded from training crawls. It is not a retroactive deletion mechanism.
 Claude-SearchBot robots.txt Rules
 Claude-User robots.txt and User-Requested Access
 Block Claude Crawlers robots.txt Template
 ClaudeBot vs Claude-SearchBot vs Claude-User
 How to Block AI Crawlers with robots.txt